Don’t Let Claude Grade Its Own Homework
I had a handful of parallel Claude agents write me up a strategy folder for a side project. The pull request looked great: ten documents, all neatly cross-linked, and it…
I had a handful of parallel Claude agents write me up a strategy folder for a side project. The pull request looked great: ten documents, all neatly cross-linked, and it…
Across 101 enterprises, agent orchestration is consolidating onto model-provider platforms — Anthropic’s Claude leads by a wide margin — chosen for the gravity of the underlying model and judged on…
Parts 1–3 of this series showed that separating IO, pipeline, and compute concerns into composable components simplifies development without sacrificing performance. This post demonstrates how Structured Mojo Kernels benefits persist…
Introduction The H100, Nvidia’s latest GPU, is a powerhouse built for AI, boasting 80 billion transistors—six times more than the previous A100. This allows it to handle massive data loads…
Today, Google DeepMind released DiffusionGemma — an experimental open model built for exceptionally fast text generation. NVIDIA has optimized DiffusionGemma to run even faster across NVIDIA GeForce RTX GPUs, the NVIDIA RTX PRO platform and NVIDIA DGX Spark systems, from local PCs to the cloud. …
The open-weights model from Thinking Machines Lab is available through the Unity AI Gateway, to build agents and applications by Mike Eastham, Yuchen Jin and Preslav Le We are excited…
Listen to the article 8 min This audio is auto-generated. Please let us know if you have feedback. The $21 billion acquisition of Exact Sciences marked Abbott’s entry into cancer…
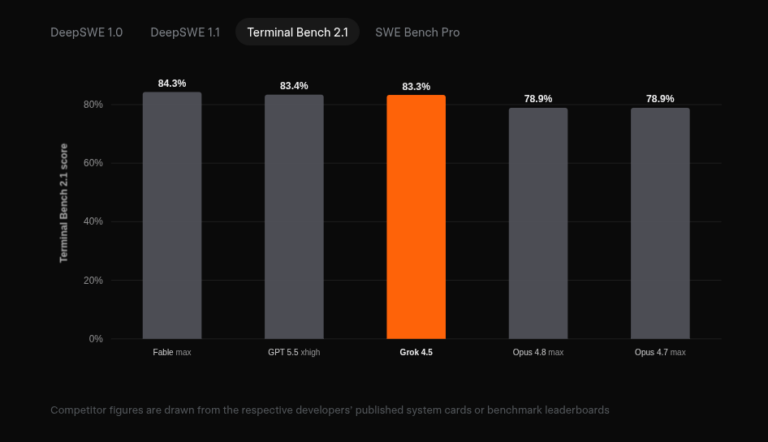
Elon Musk’s SpaceXAI Corp. has released a new model called Grok 4.5, in what is its first major launch since it went public a few weeks earlier. In a blog…
# Introduction Every Python codebase has this problem. A function that starts small. Two branches, maybe three. Then someone adds a case, someone else adds another, and a year later…
We’ve spent the last several weeks shipping a set of changes to Together GPU Clusters aimed at the operational reality of running training and inference at scale: hardware fails, schedulers…